To make the system self-improving, we built an automated Scenario Synthesizer, Agent Evaluator, and Protocol Optimizer. This approach generates diverse test cases, identifies structural reasoning errors, and updates the APB iteratively.
The result is a closed learning loop: the agent observes its own decision patterns, corrects them, and strengthens its logic — all without manual retraining. Over time, it becomes more robust in its capabilities, more policy-compliant, and more aligned with human expectations.
This approach turns AI from a static model into a self-improving system that can evolve through experience, much like a skilled employee refining judgment through feedback.
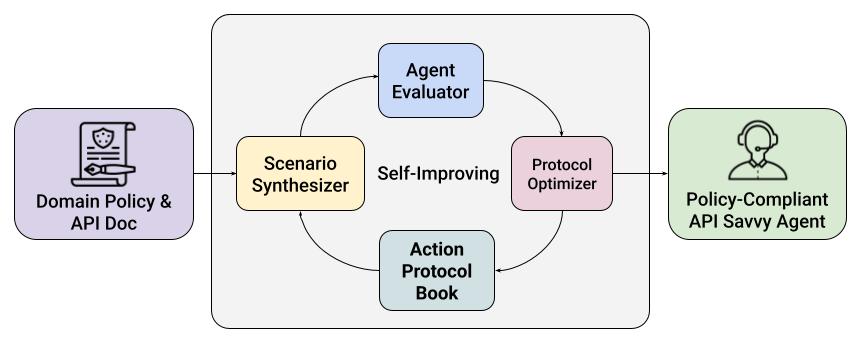
In production environments for customer service solutions like Zoom Virtual Agent, the same architecture delivers more reliable, policy‑compliant, and continuously improving customer interactions.





 6 min read